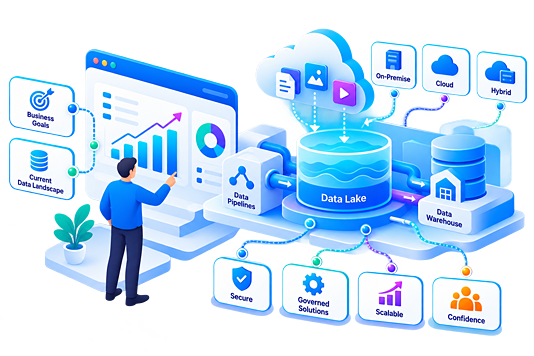
End-to-End Data Solutions
From data collection and cleaning to storage and advanced analytics, a comprehensive suite of services to manage the full lifecycle of your data, including data migration and maintaining data integrity.
Talk to our teamTurn complex data into actionable insights with efficient, AI-augmented data pipelines, from data ingestion to real-time analytics.
Technologies and industries we work with
As data grows exponentially, it becomes increasingly difficult to make sense of it without the right systems in place. We put those systems in place.
Efficient data ingestion and transformation pipelines that handle the growing complexity of data in various formats, built with cloud-based ETL tools.
Decouple compute and storage via Snowflake, BigQuery, and Databricks. Implement Iceberg and Delta Lake for ACID transactions at scale.
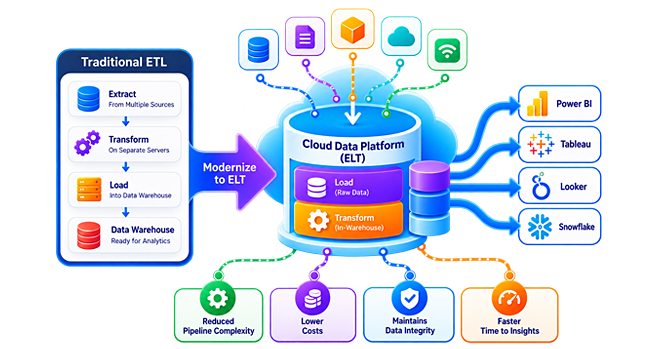
Load raw data into your cloud data platform first, then transform it there with scalable SQL. Data arrives faster, models are easier to change, and processing scales with the platform instead of separate servers.
Fault-tolerant micro-batch and streaming ingestion with schema validation built on Kafka, Spark, and cloud-native serverless orchestrators.
Transform centralized data teams into domain-driven data products with automated lineage, contract testing, and role-based masking.
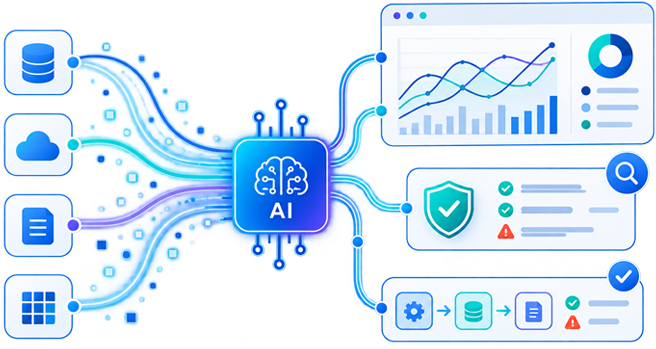
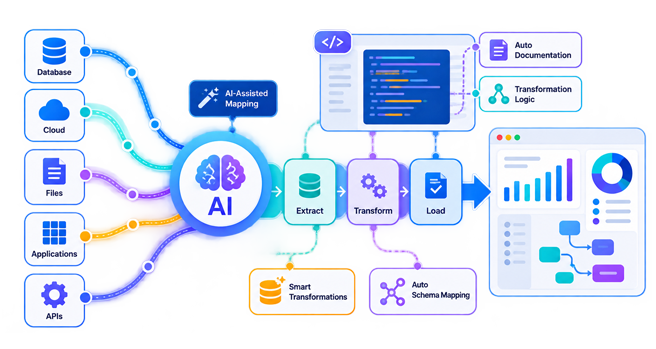
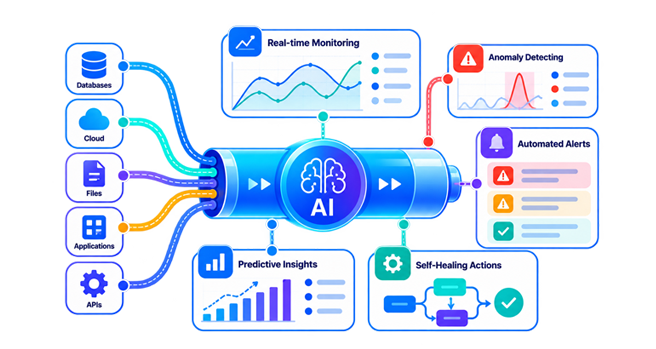
We bring AI into the data engineering lifecycle, using machine learning and generative AI to make pipelines smarter, faster to build and easier to run.
AI-driven checks spot anomalies, schema drift and bad records early, before they reach your reports.
AI-assisted mapping, transformation logic and documentation shorten the time it takes to onboard new data sources.
Pipelines that learn normal behaviour, flag failures early and help teams resolve issues faster.
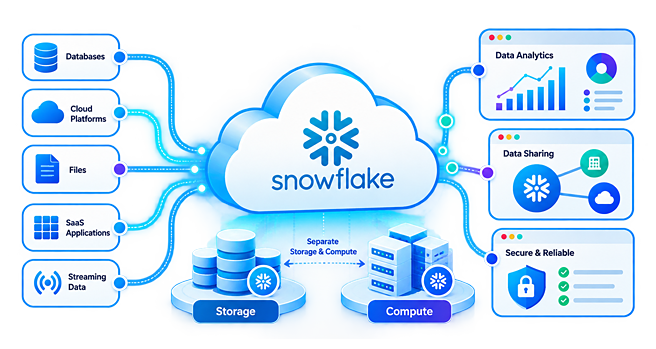
Snowflake is a cloud data platform that separates storage and compute, so performance and cost can scale independently. We design, build and migrate Snowflake environments that keep your data fast, reliable and easy to share.
Databases, virtual warehouses, roles and security designed around your workloads, teams and budget.
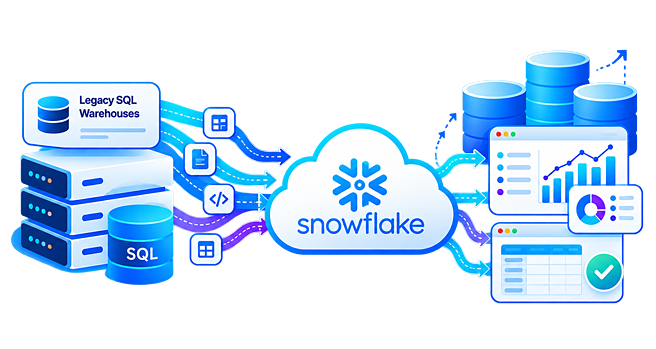
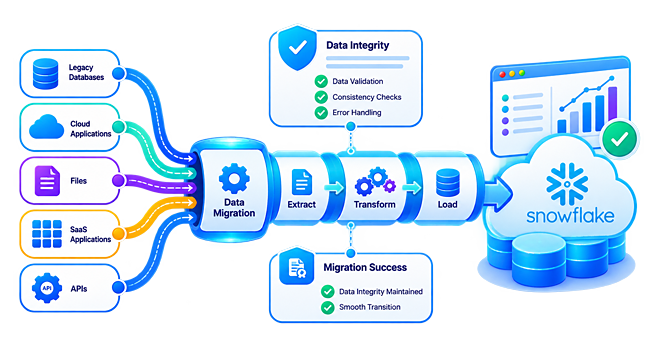
Move data and logic from legacy SQL-based warehouses to Snowflake while maintaining data integrity.
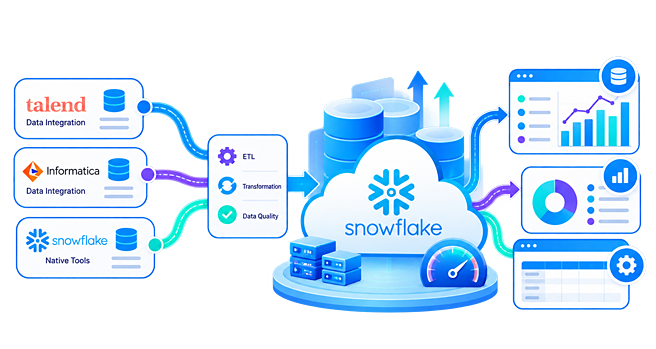
Load data with Talend, Informatica or native Snowflake tools, and tune queries and warehouse sizing for speed and cost.
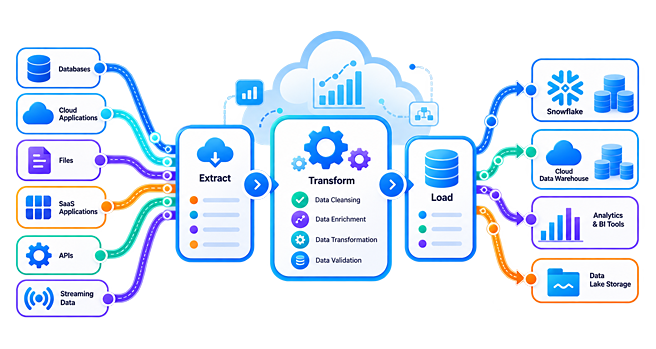
Effective data engineering involves building efficient ETL (Extract, Transform, and Load) data pipelines that can handle the growing complexity of data in various formats.
We have extensive expertise in cloud-based ETL tools, including industry-leading platforms like Talend.
We streamline the process of data extraction, transformation, and loading so your teams get analysis-ready data faster.
We simplify data migration while maintaining data integrity across every step of the pipeline.

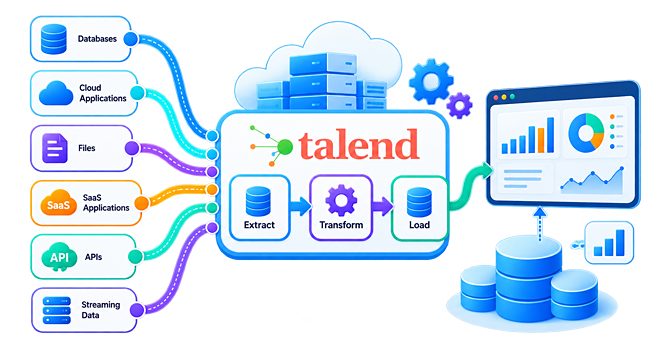
Talend is a powerful open-source ETL tool at the heart of many of our data engineering projects, helping businesses optimize data processes and make data-driven decisions.
Integrate data from multiple sources and transform it for use in analytics and business intelligence.
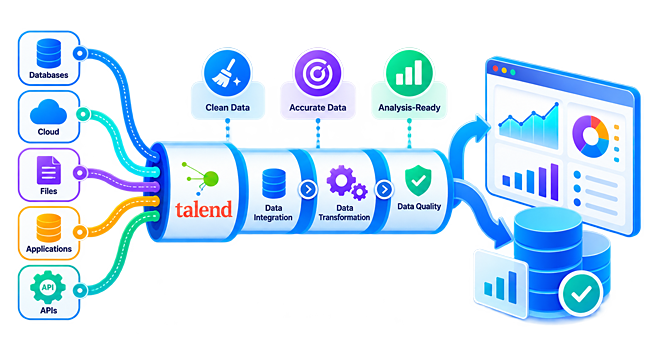
Our team has years of experience implementing Talend for data integration, migration and transformation, ensuring your data is clean, accurate and ready for analysis while maintaining data quality.
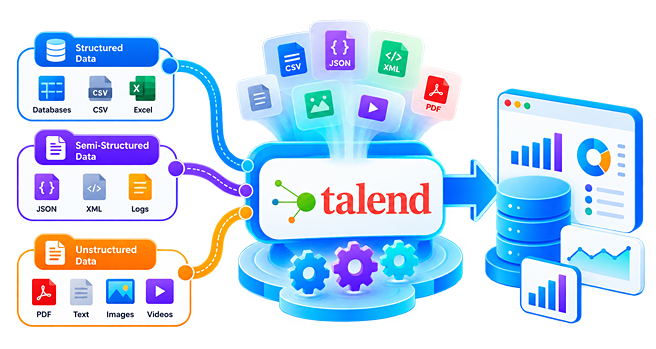
Structured, semi-structured or unstructured, Talend provides the flexibility to handle diverse data types efficiently.
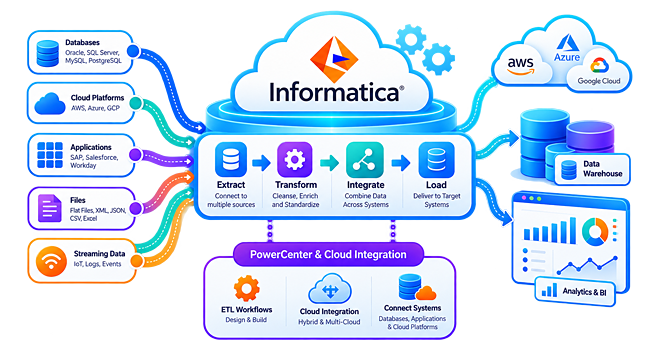
Informatica is an enterprise-grade platform for high-volume data integration and data management. We design, build and modernize Informatica pipelines that keep your data accurate, governed and ready for analytics.
We build and maintain ETL workflows in Informatica PowerCenter and Informatica cloud data integration, connecting databases, applications and cloud platforms.
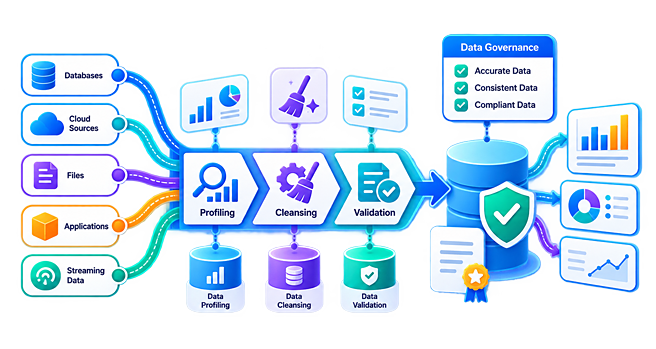
Profiling, cleansing and validation rules keep data consistent, accurate and compliant across your pipelines.
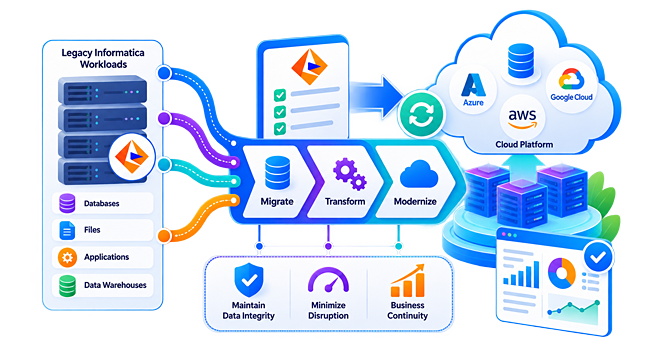
We move legacy Informatica workloads to the cloud while maintaining data integrity and minimizing disruption to the business.
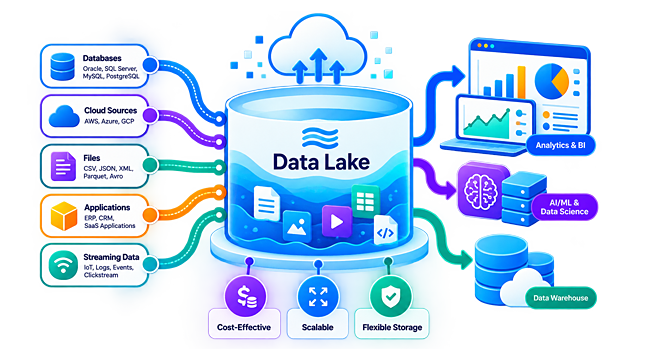
Data lakes are a key pillar of modern data engineering: centralized repositories that store vast amounts of raw, unstructured data from diverse sources.
Store raw data from diverse sources in a cost-effective and scalable manner.
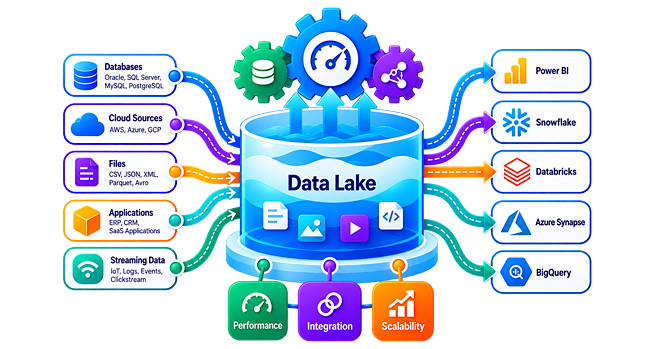
Our data lakes are optimized for performance and integrate seamlessly with other data tools and systems.
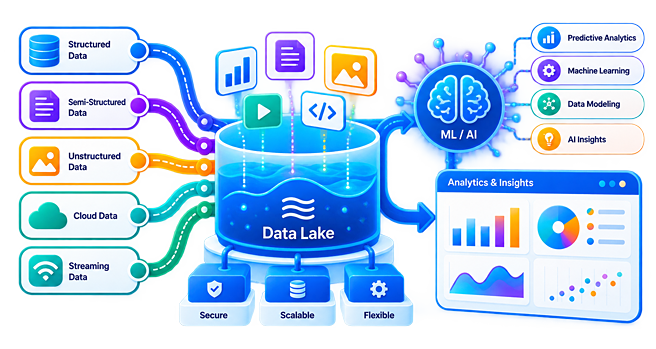
A robust, secure and flexible architecture lets you leverage all types of data for advanced analytics and machine learning.
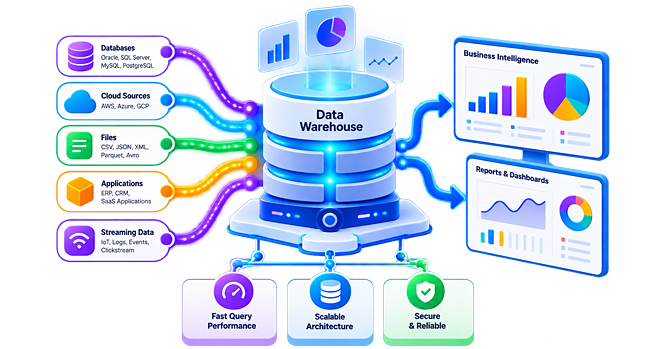
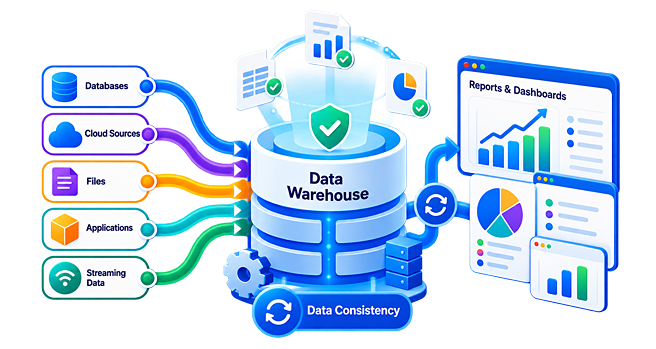
Data warehouses store structured, processed data optimized for reporting and business intelligence, designed around the unique needs of your business.
Our warehouse solutions deliver fast query performance so reports and dashboards stay responsive.
Data consistency and seamless integration with your reporting tools keep everyone working from reliable numbers.
Whether you use traditional SQL-based systems or modern cloud warehouses like Snowflake, your data stays organized, reliable and accessible.
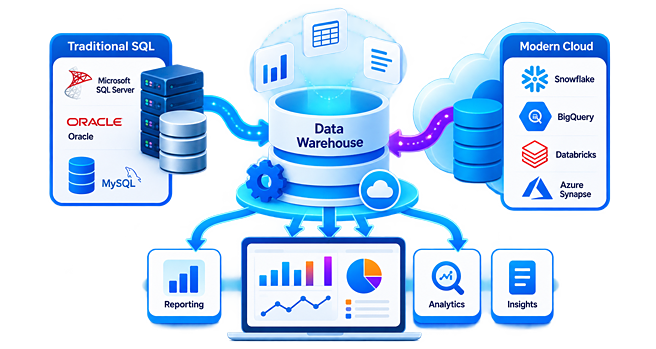
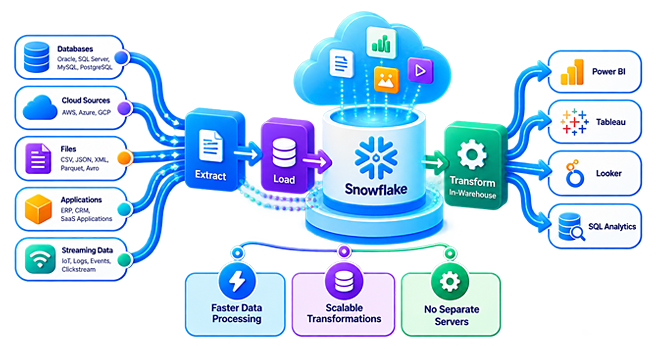
ELT (Extract, Load, Transform) lands raw data in your cloud warehouse first, then transforms it there using the platform's own compute. Data arrives faster, models are easier to change, and processing scales with platforms like Snowflake.
Raw data lands quickly in Snowflake or your cloud data platform, then scalable SQL transforms it right where it lives, with no separate processing servers to manage.
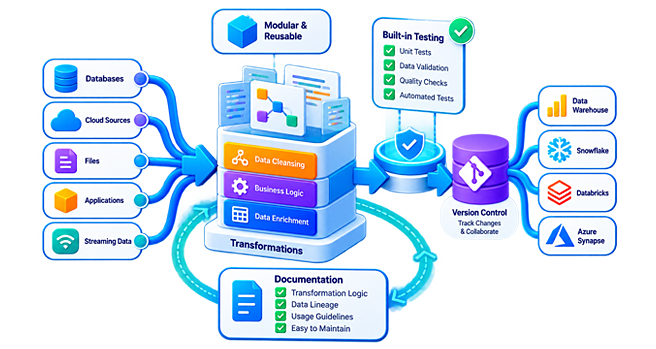
Version-controlled transformation models with built-in tests and documentation keep business logic reliable, reusable and easy to change.
We move legacy ETL workloads to an ELT approach, reducing pipeline complexity and cost while maintaining data integrity.
We are committed to helping organizations unlock the true potential of their data. Here's why our clients choose us.
From data collection and cleaning to storage and advanced analytics, a comprehensive suite of services to manage the full lifecycle of your data, including data migration and maintaining data integrity.
Talk to our team
We integrate data from multiple sources, including databases, APIs and cloud services, to create unified datasets for analysis.

Our data governance practice prioritizes data quality and consistency, so your data is reliable and compliant with industry standards.

Scalable, secure data solutions that work across on-premise, cloud and hybrid environments with robust pipelines.

We tune existing data pipelines for speed, reliability and cost, with faster loads, fewer failures and right-sized compute.
Strong data governance keeps your data accurate, consistent and compliant with industry standards, from the first pipeline to the final report.

Fabric-ready real-time fraud analytics
A provider of facial recognition and liveness detection for secure identity proofing faced exponential growth in verification requests and needed near real-time insight into transaction patterns and fraud vectors. DEFTeam built a cloud-native analytics platform on the Microsoft data stack, using the same building blocks Microsoft Fabric unifies: real-time event ingestion, Data Factory pipelines and Synapse data warehousing.
fraud pattern analysis and operational reporting, strengthening fraud prevention and service reliability at scale

Legacy census system modernization
DEFTeam successfully modernized a legacy census system by architecting a robust data warehouse and implementing a robust ETL process using Talend.
decision-making enabled through efficient data pipelines and data migration, unlocking the full potential of their data
Everything you need to know about our data architecture services, modern stack migration, and AI-augmented data pipelines.
We design and build modern data platforms end to end: data ingestion, ETL and ELT pipelines, AI-augmented data pipelines, data lakes, data warehouses on platforms like Snowflake, and Big Data solutions. Our team works with Talend, Informatica and leading cloud services to integrate data from databases, APIs and cloud applications into unified, analysis-ready datasets.
We start by assessing your existing jobs, mappings and dependencies, then plan a phased move to a modern cloud stack. Data is validated at every stage so integrity is maintained, and legacy and new pipelines can run side by side until cut-over, keeping disruption to the business to a minimum.
We review query patterns, data models and warehouse sizing, then tune partitioning, clustering and caching, right-size compute, and set up auto-suspend and usage monitoring. The result is faster queries for your teams without paying for idle capacity.
They are pipelines that use machine learning and generative AI to make data engineering smarter: detecting anomalies and schema drift before bad data reaches reports, speeding up mapping and transformation development, and flagging failures early so teams can resolve issues faster.
We build data ingestion pipelines that capture data from databases, APIs, applications and event streams, in scheduled batches, micro-batches or real time. Schema validation and fault-tolerant processing on Kafka, Spark and cloud-native serverless orchestrators keep incoming data accurate and complete.
We build data governance into every platform from the start: data quality checks, consistent definitions, automated lineage, role-based access and masking, and audit-ready controls. Your data stays reliable, secure and compliant with industry standards as it scales.
Yes. We build scalable, secure data solutions that work across on-premise, cloud and hybrid environments, including multi-cloud setups, with robust pipelines and data governance built in from the start.
Share your goals and current data landscape with our team through the contact page. We'll review your environment and recommend a practical roadmap for your pipelines, storage and analytics. Contact us